Guides
How-tos and strategic perspectives on building with small language models.
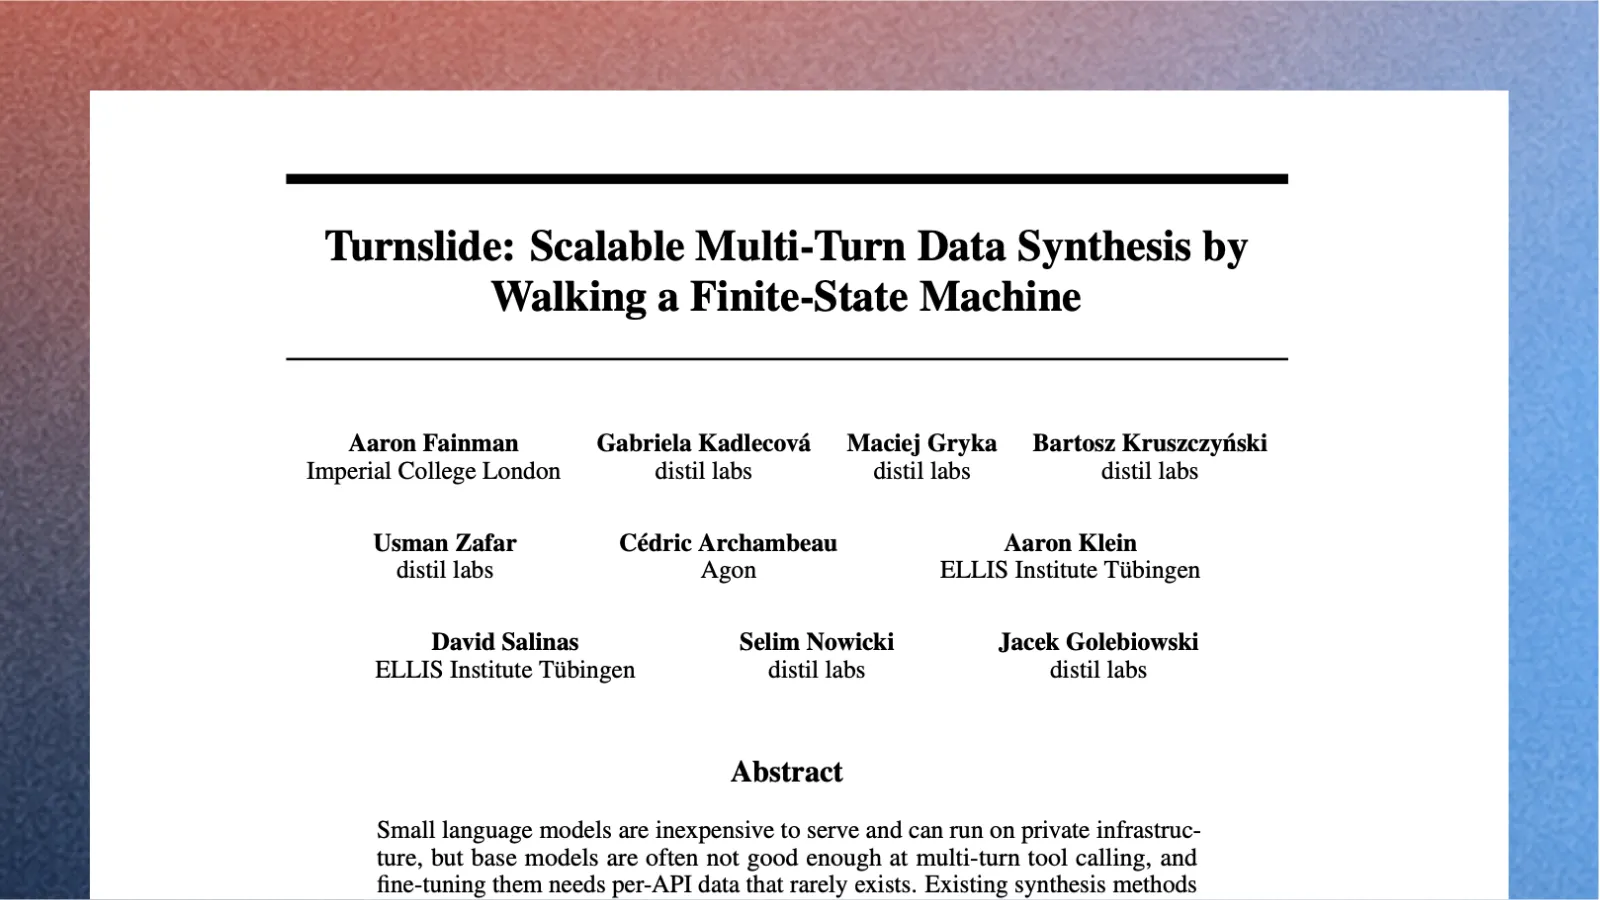
Our research paper was accepted to the SLM-Agents workshop at NeurIPS 2026
Our research paper on generating multi-turn tool-calling training data for small language models has been accepted to the SLM-Agents workshop at NeurIPS 2026. Read the abstract and download the paper.
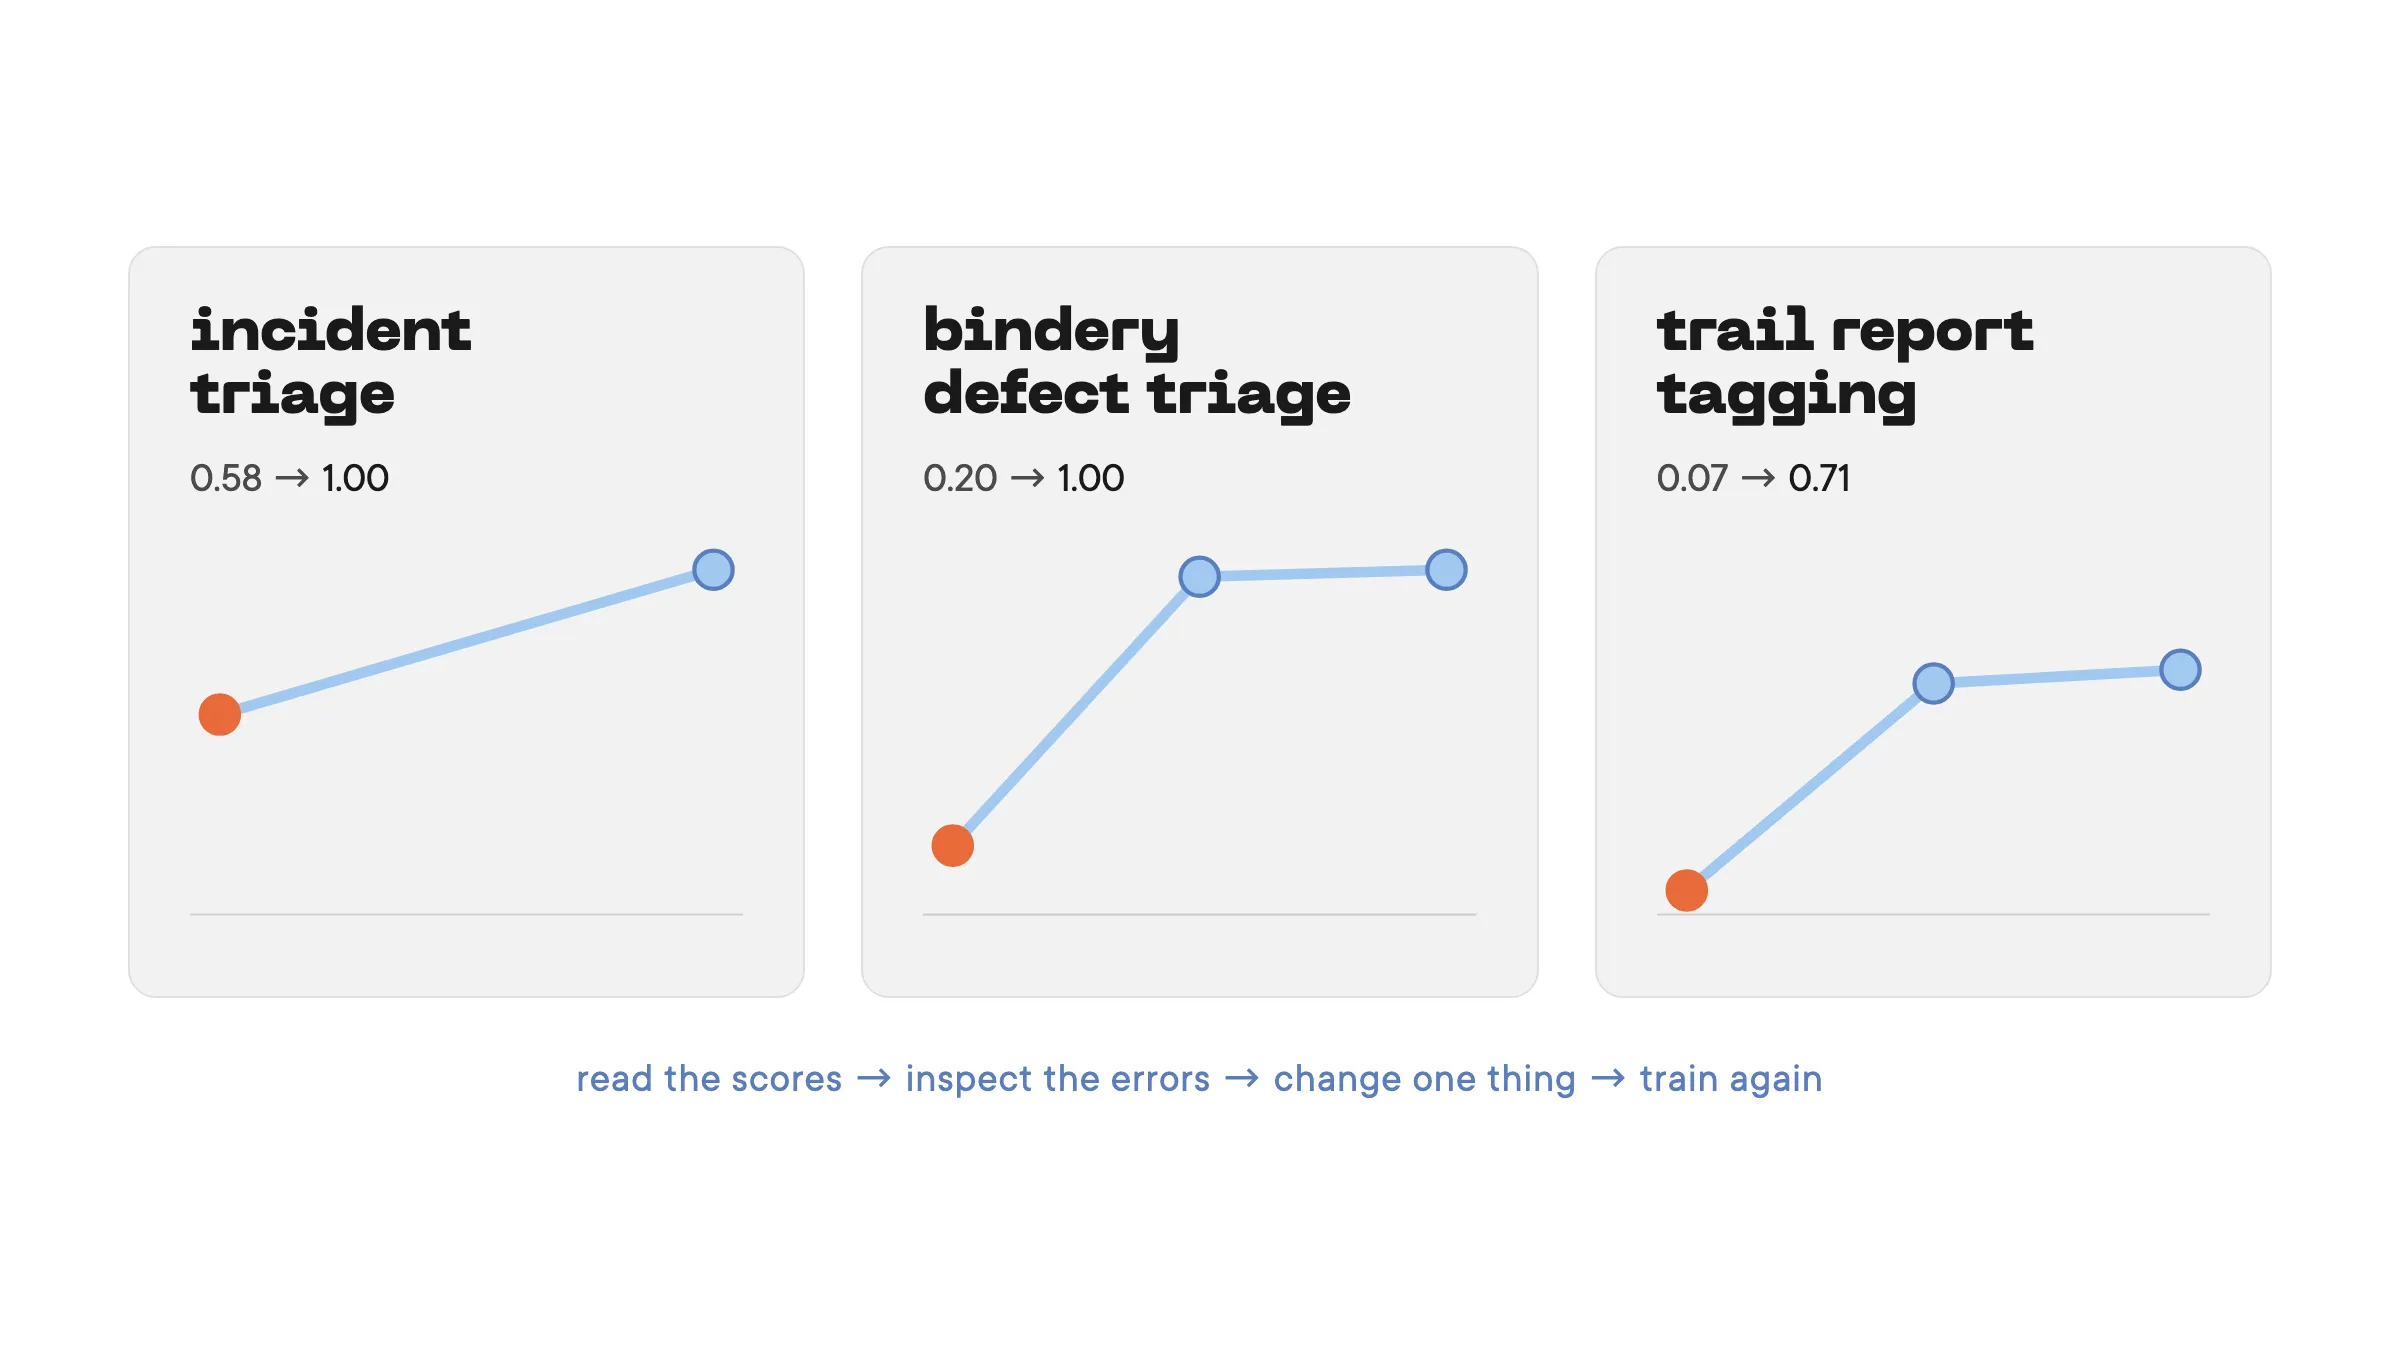
Autoresearch with distil labs: let your agent iterate on building SLMs for your case
We gave three coding agents the distil labs skill and a budget of three training runs. Two 0.6B students reached their 120B teacher and the third beat the production service it replaces, with no human in the loop.
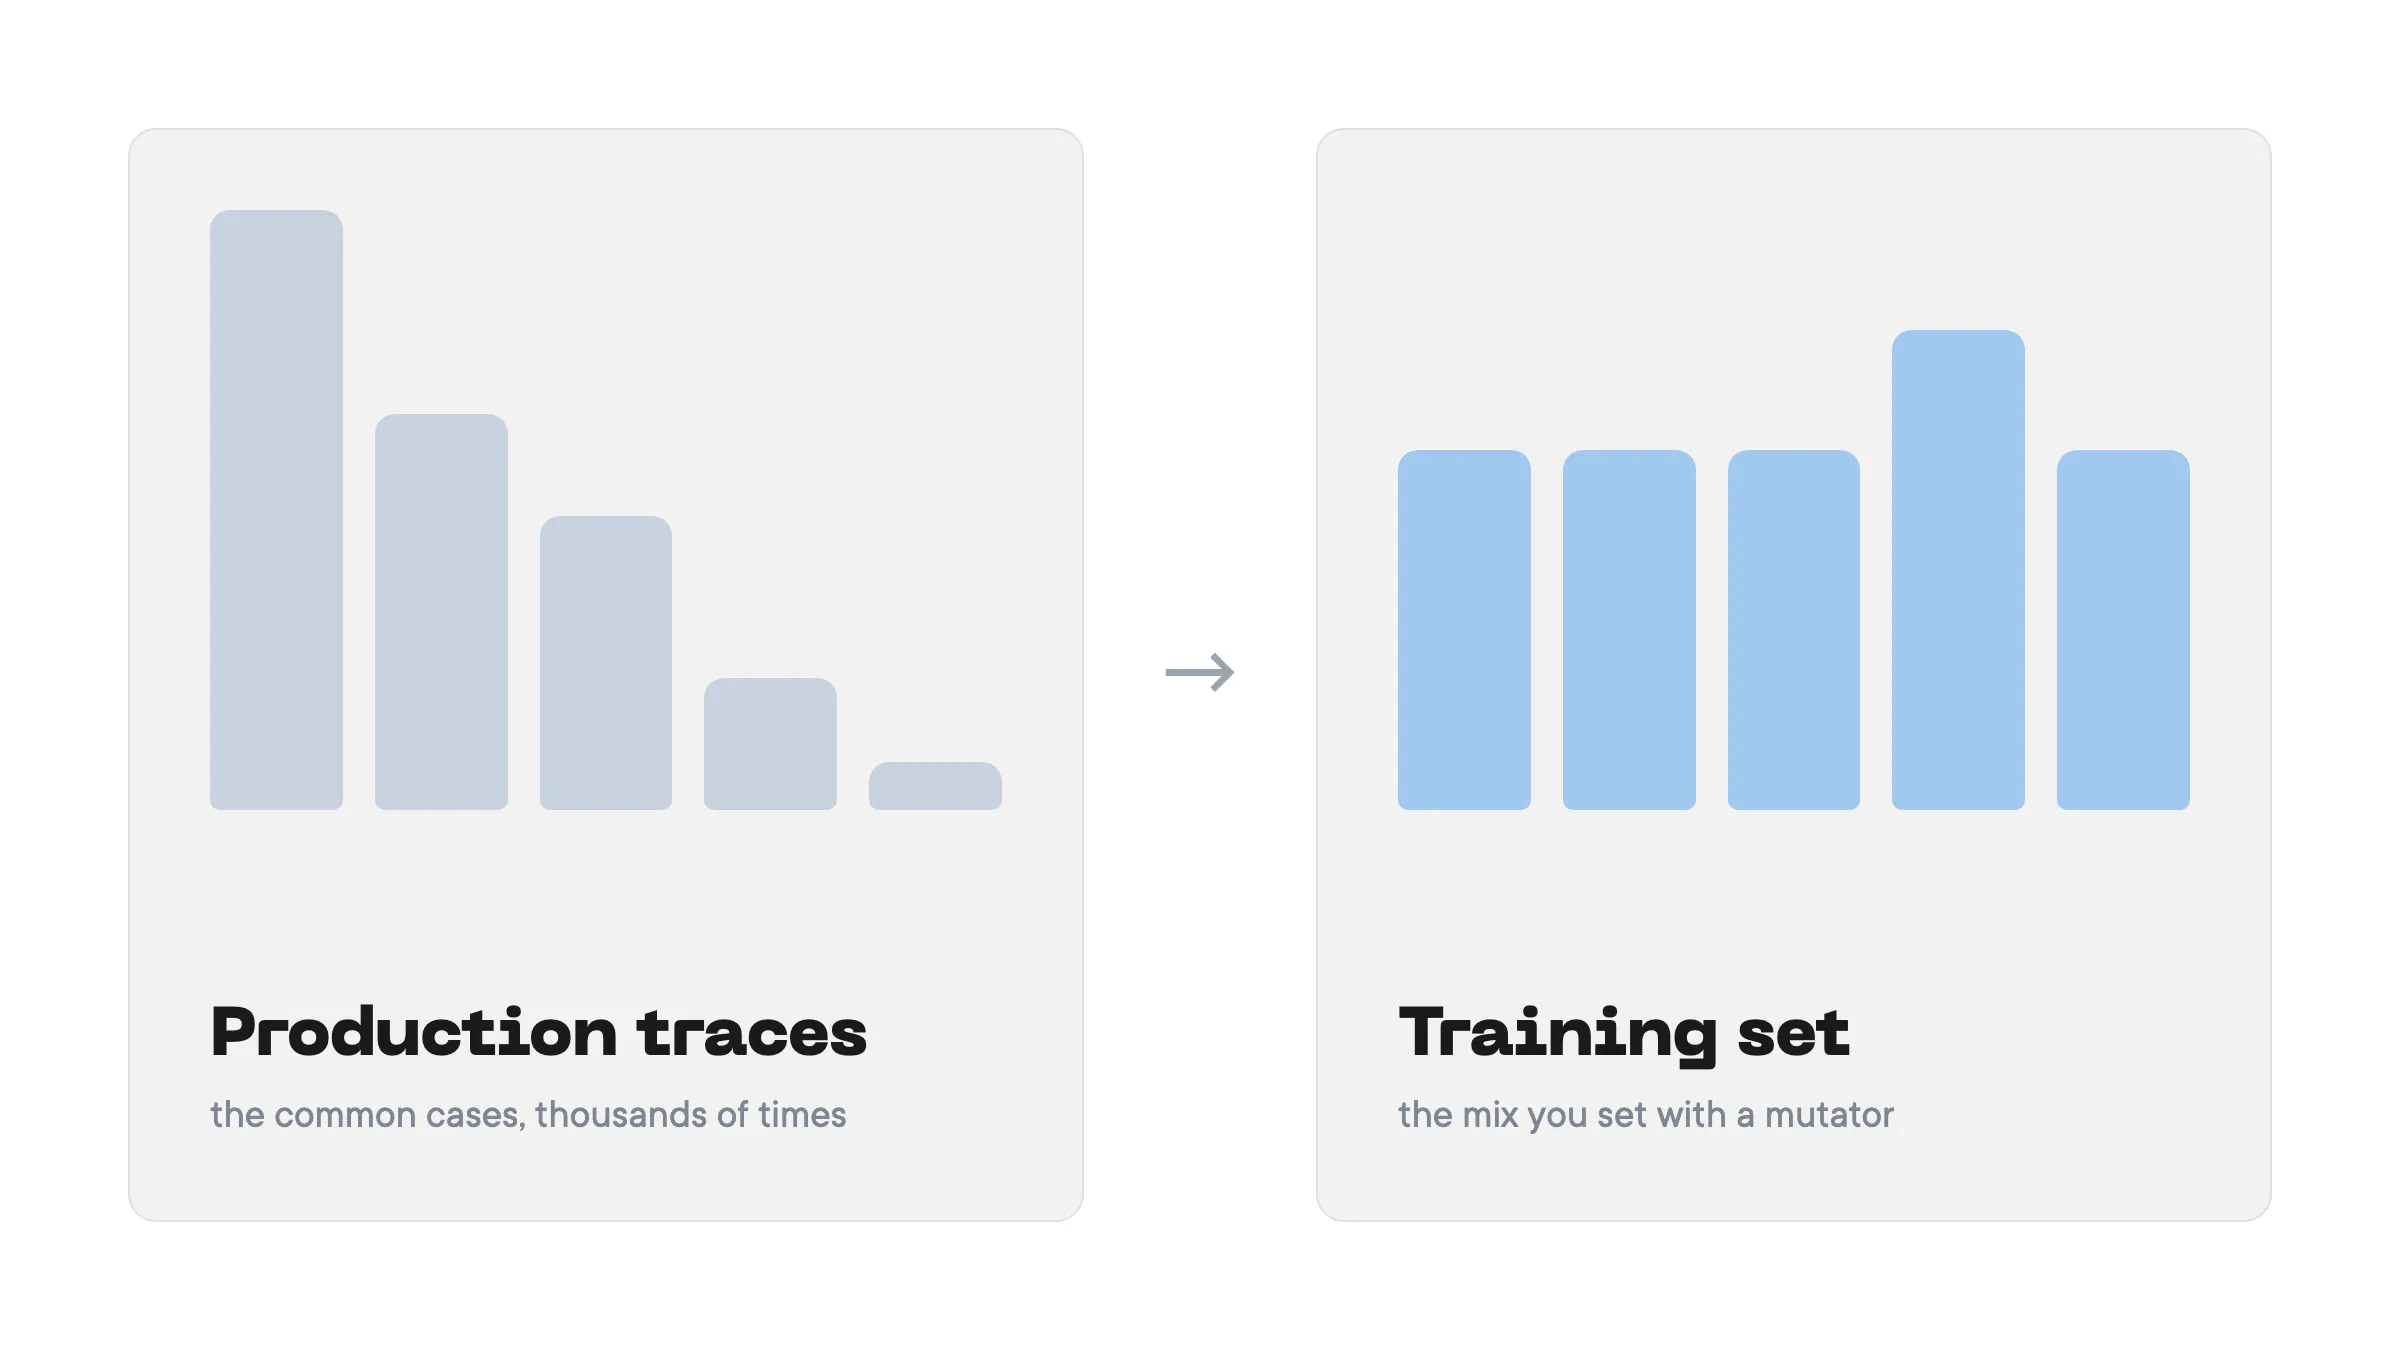
Mutators: set the mix of your synthetic dataset
Set which situations your synthetic training data covers and how often each appears. A support-assistant benchmark compares fixed and adaptive mutators with unconstrained generation.
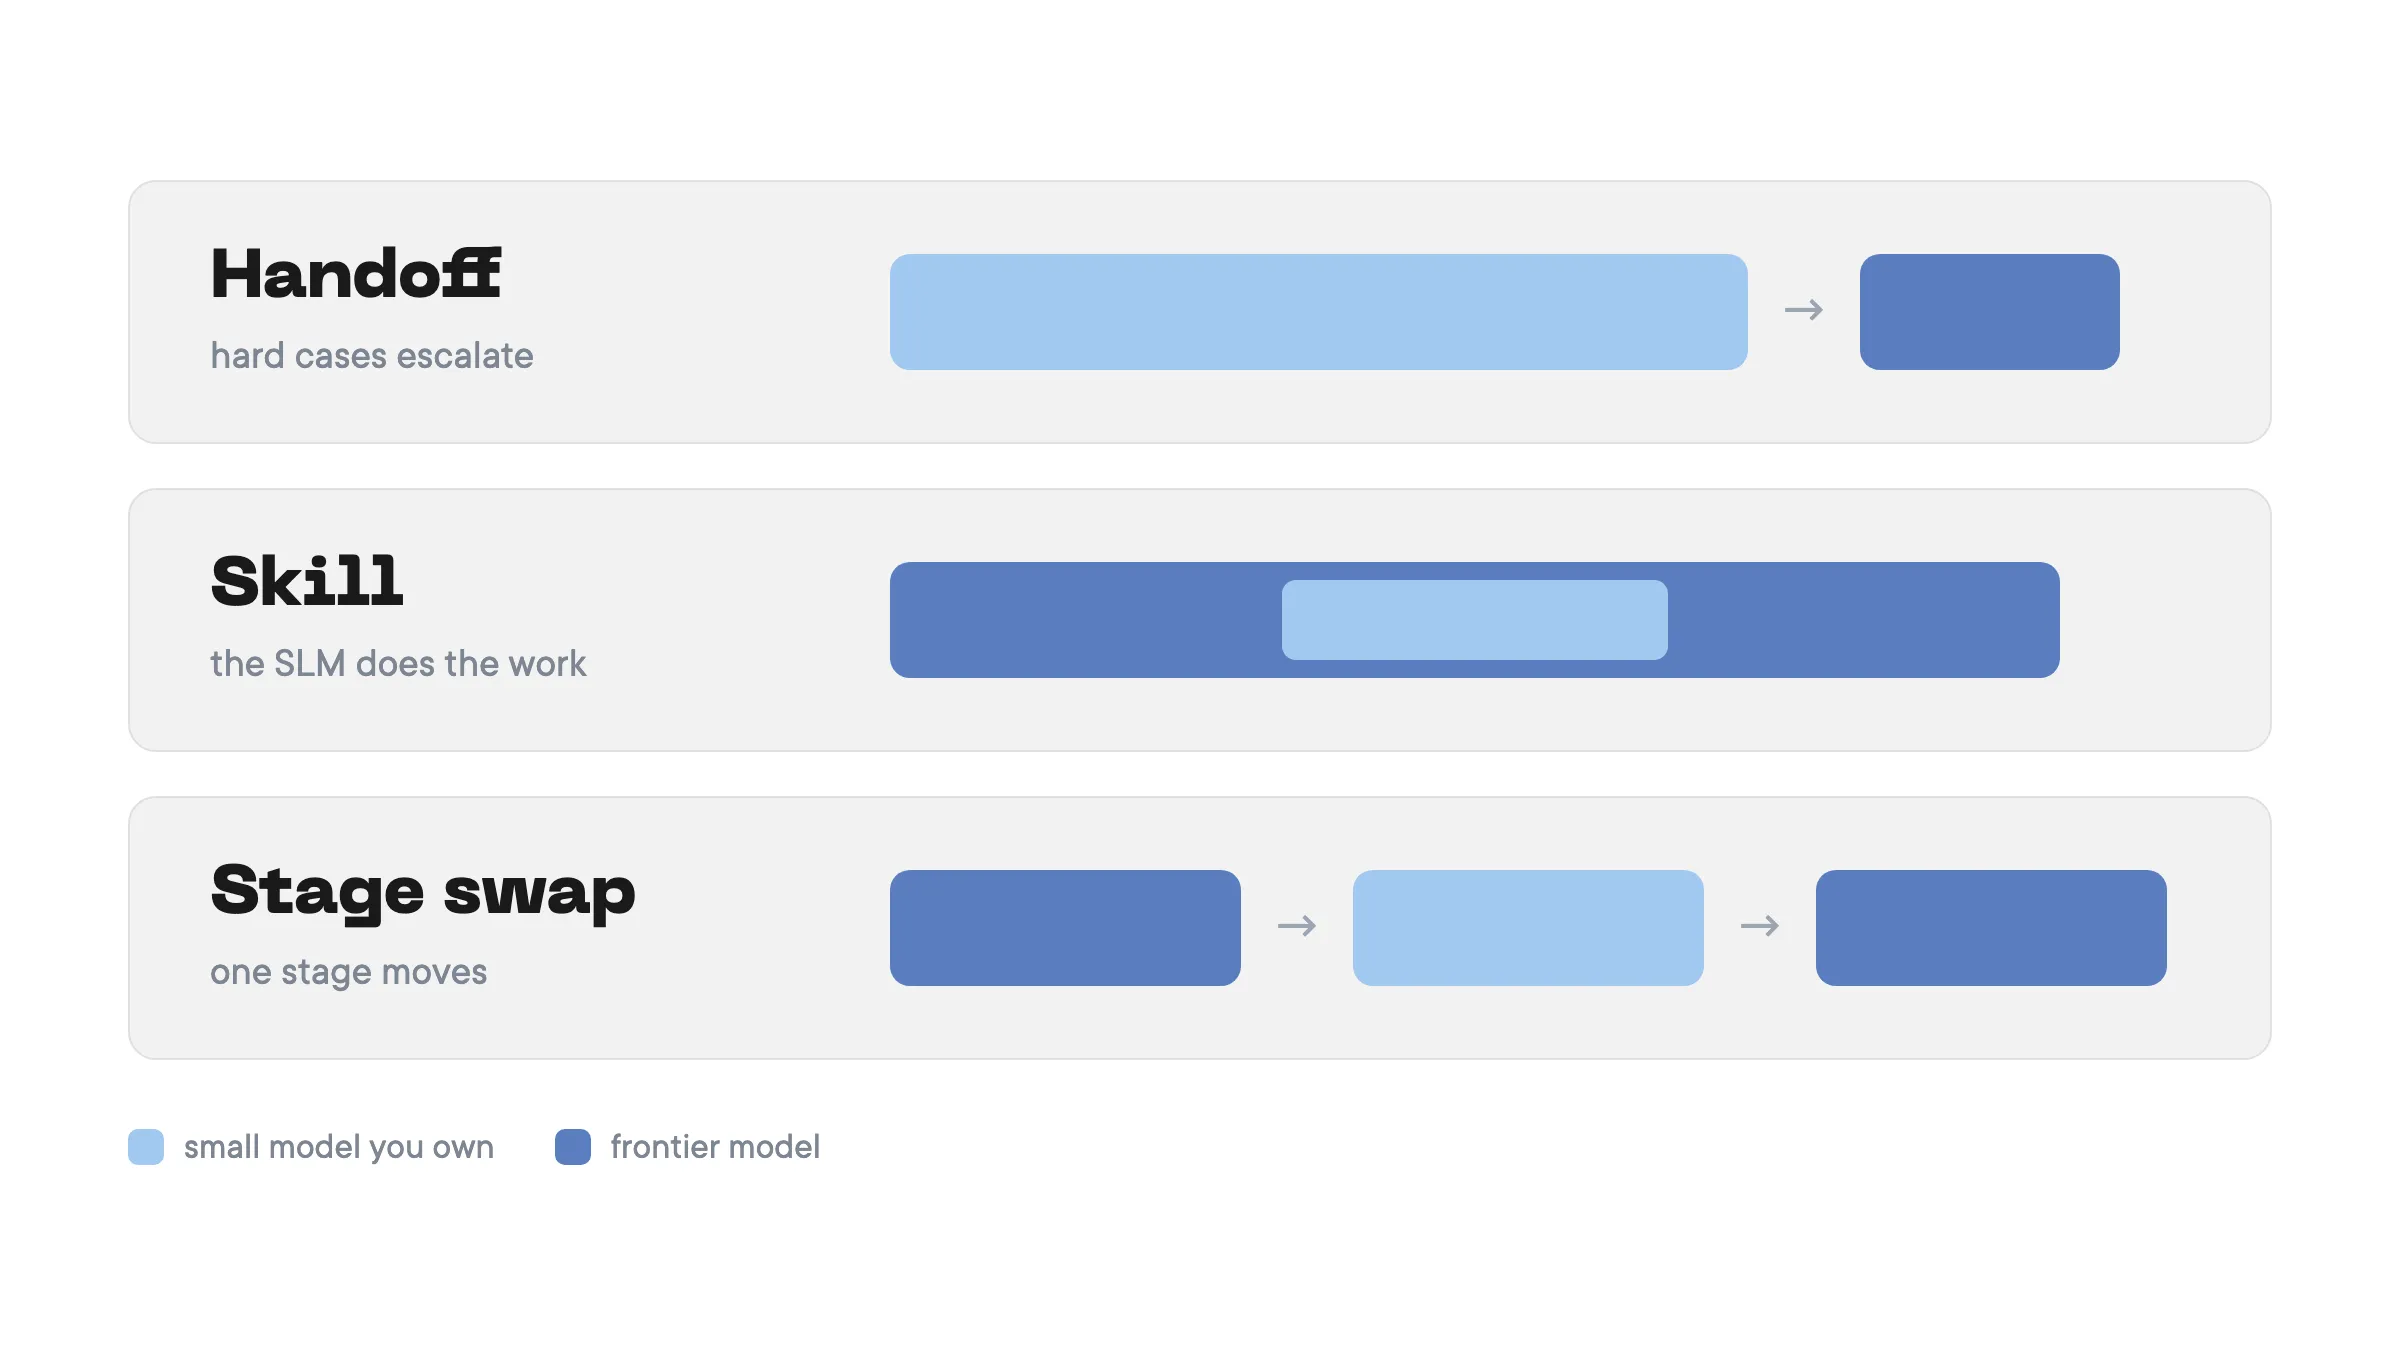
Three ways to put a small model into production
Getting a small model into production comes down to three patterns: handoff, skill, and stage swap. Which one fits is decided by where the repeated narrow work already sits in your system.
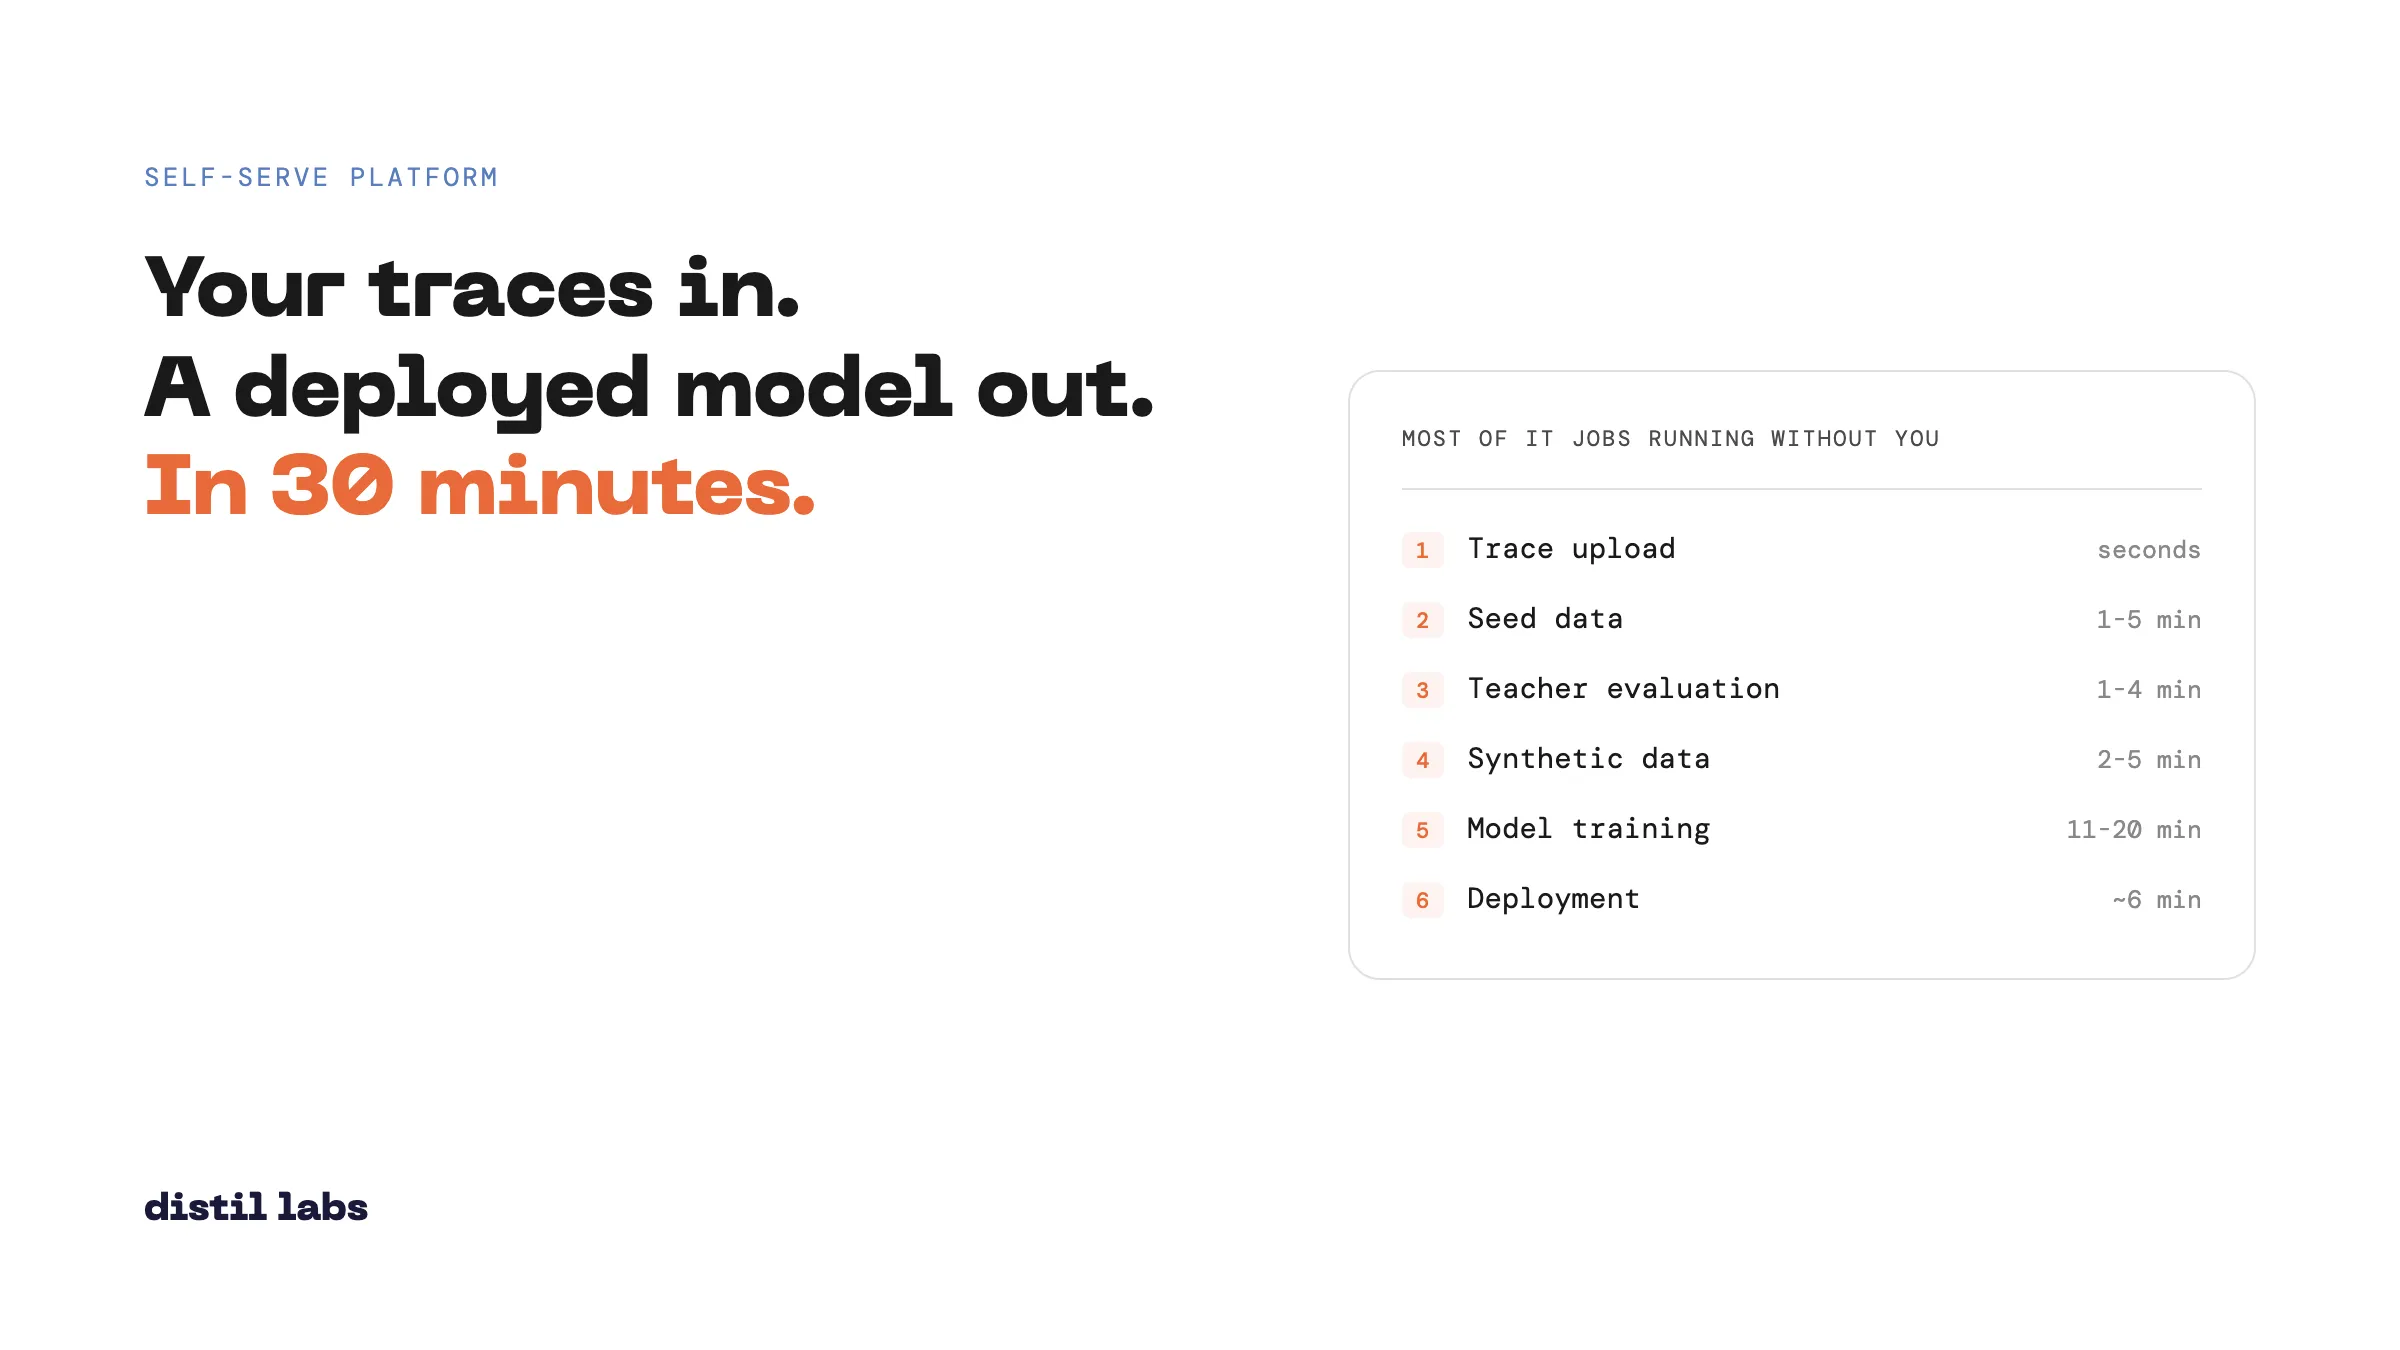
Train and deploy a small model in 30 minutes using the CLI or your coding agent
Training a task-specific small model is six stages, starting from the production traces you already collect. A first model takes about 30 minutes, and most of that is jobs running without you. You drive it from the CLI or hand it to your coding agent.
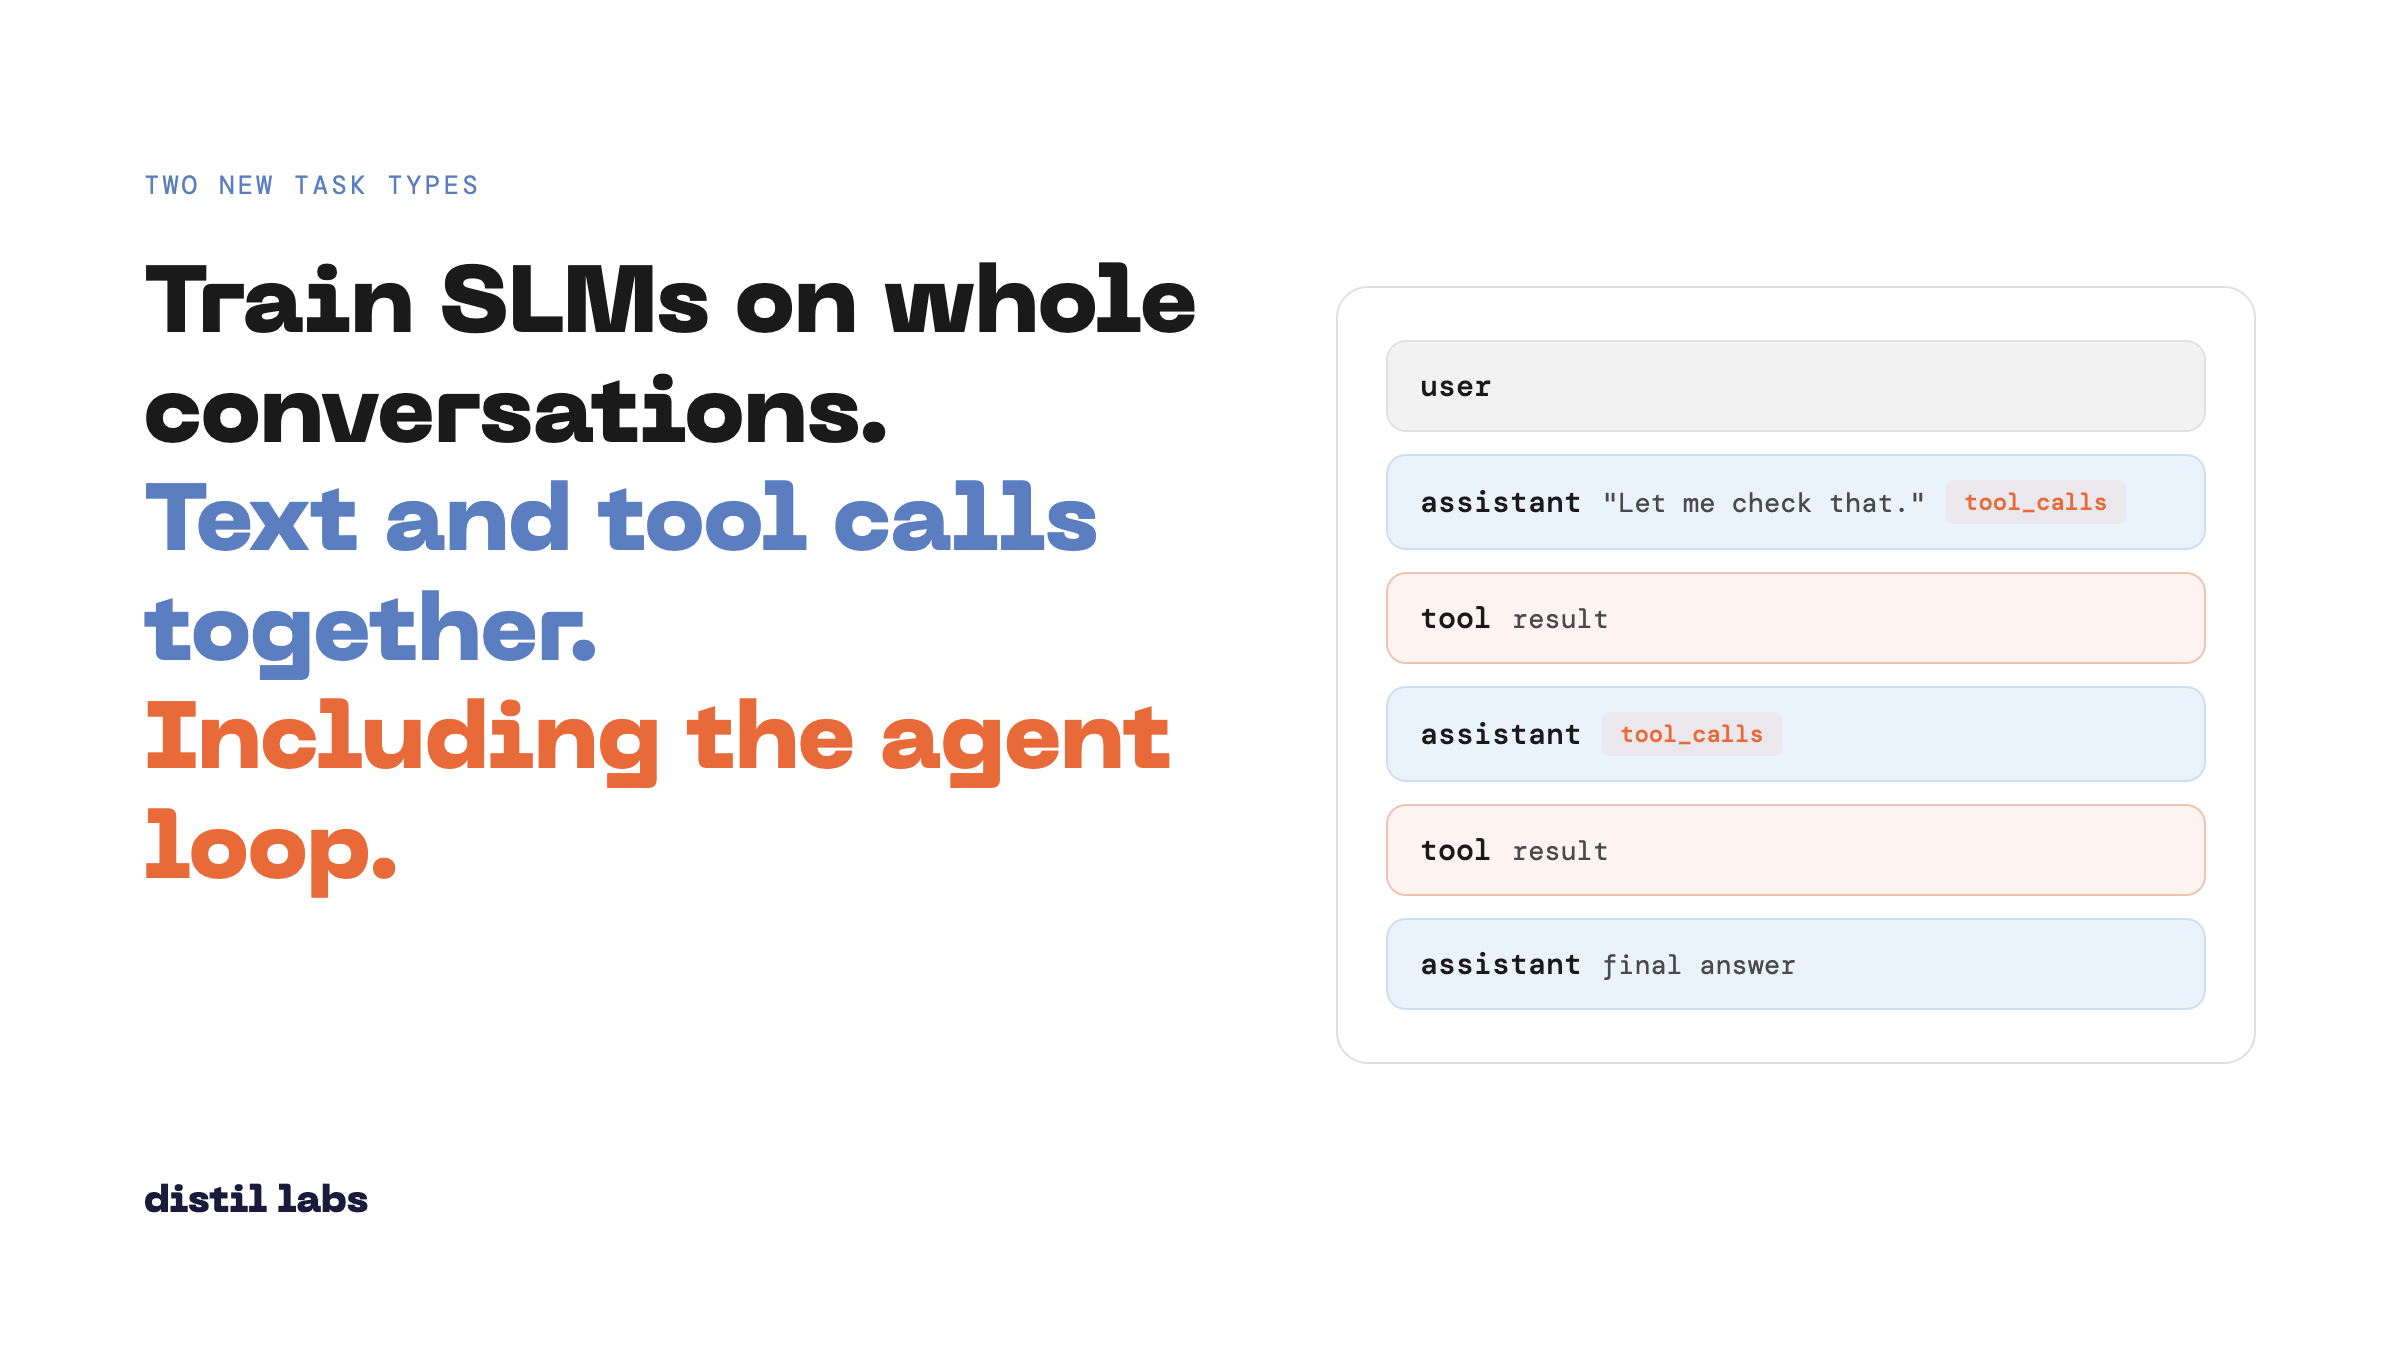
Conversations are now first-class citizens: two new task types for whole-conversation training
Two new task types, chat-completion and chat-completion-agentic, fine-tune small models on complete conversations: text and tool calls together, up to the full agent loop of calling a tool, reading the result, and deciding what to do next.
Gemini 2.5 Flash-Lite retires on a date you don't pick, and a like-for-like swap wastes the migration
Google has announced the retirement of the Gemini 2.5 series, no earlier than October 16, 2026, with the exact date to be set on Google's schedule. Every team running a narrow high-volume job on these models has to re-qualify a replacement whether they want to or not. The default move is another general-purpose workhorse, which means paying to keep the same roughly 80% accuracy on a task that is worth more than that. One education platform spent that same migration on a fine-tuned small model instead and went from 81% to 93% accuracy with inference cost down 68%.
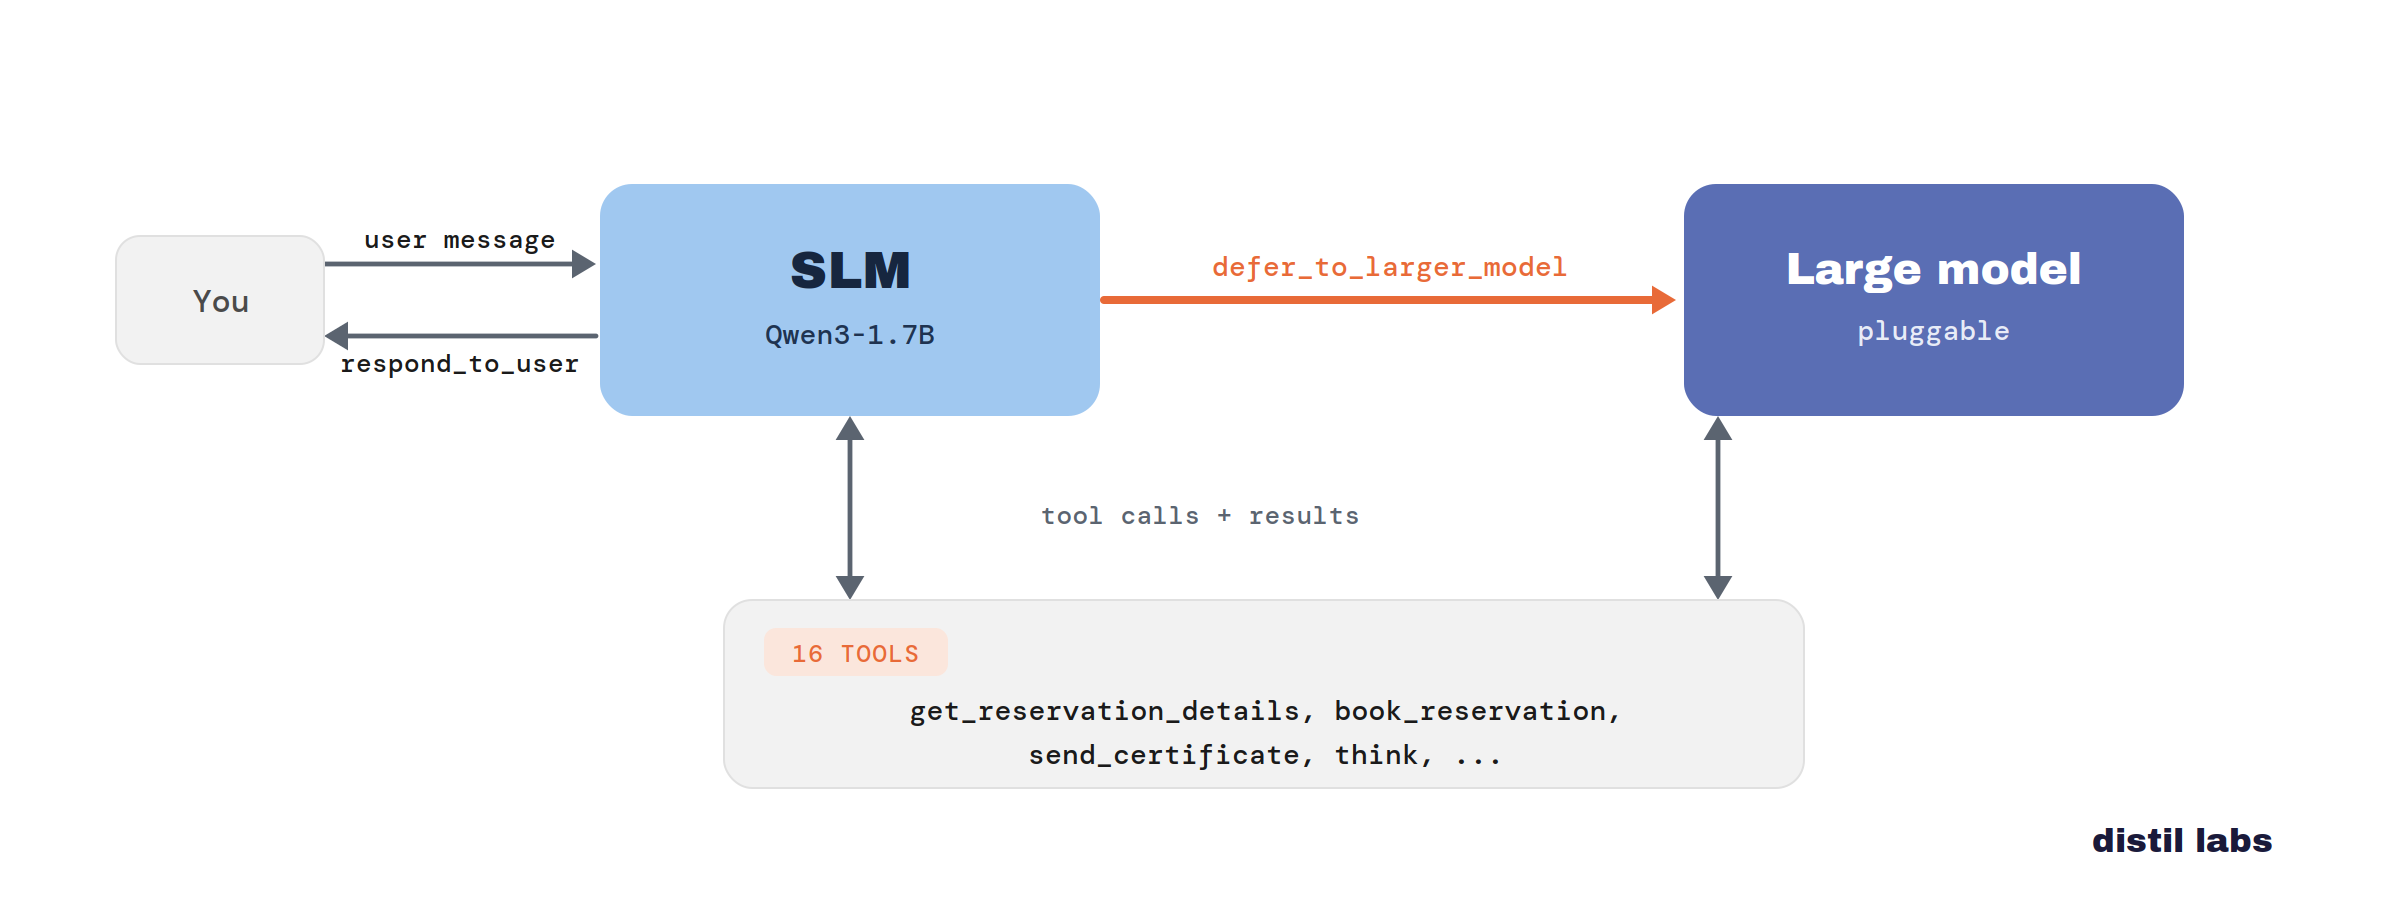
Don't Build a Router. Train the Small Model to Know When to Defer.
A fine-tuned small model handles the easy majority of customer-support turns and defers the genuinely-hard minority to a frontier model, matching all-frontier quality at a fraction of the cost. No router, no thresholds, no second classifier: the small model is trained to recognize when it's out of its depth and escalate with a single tool call.
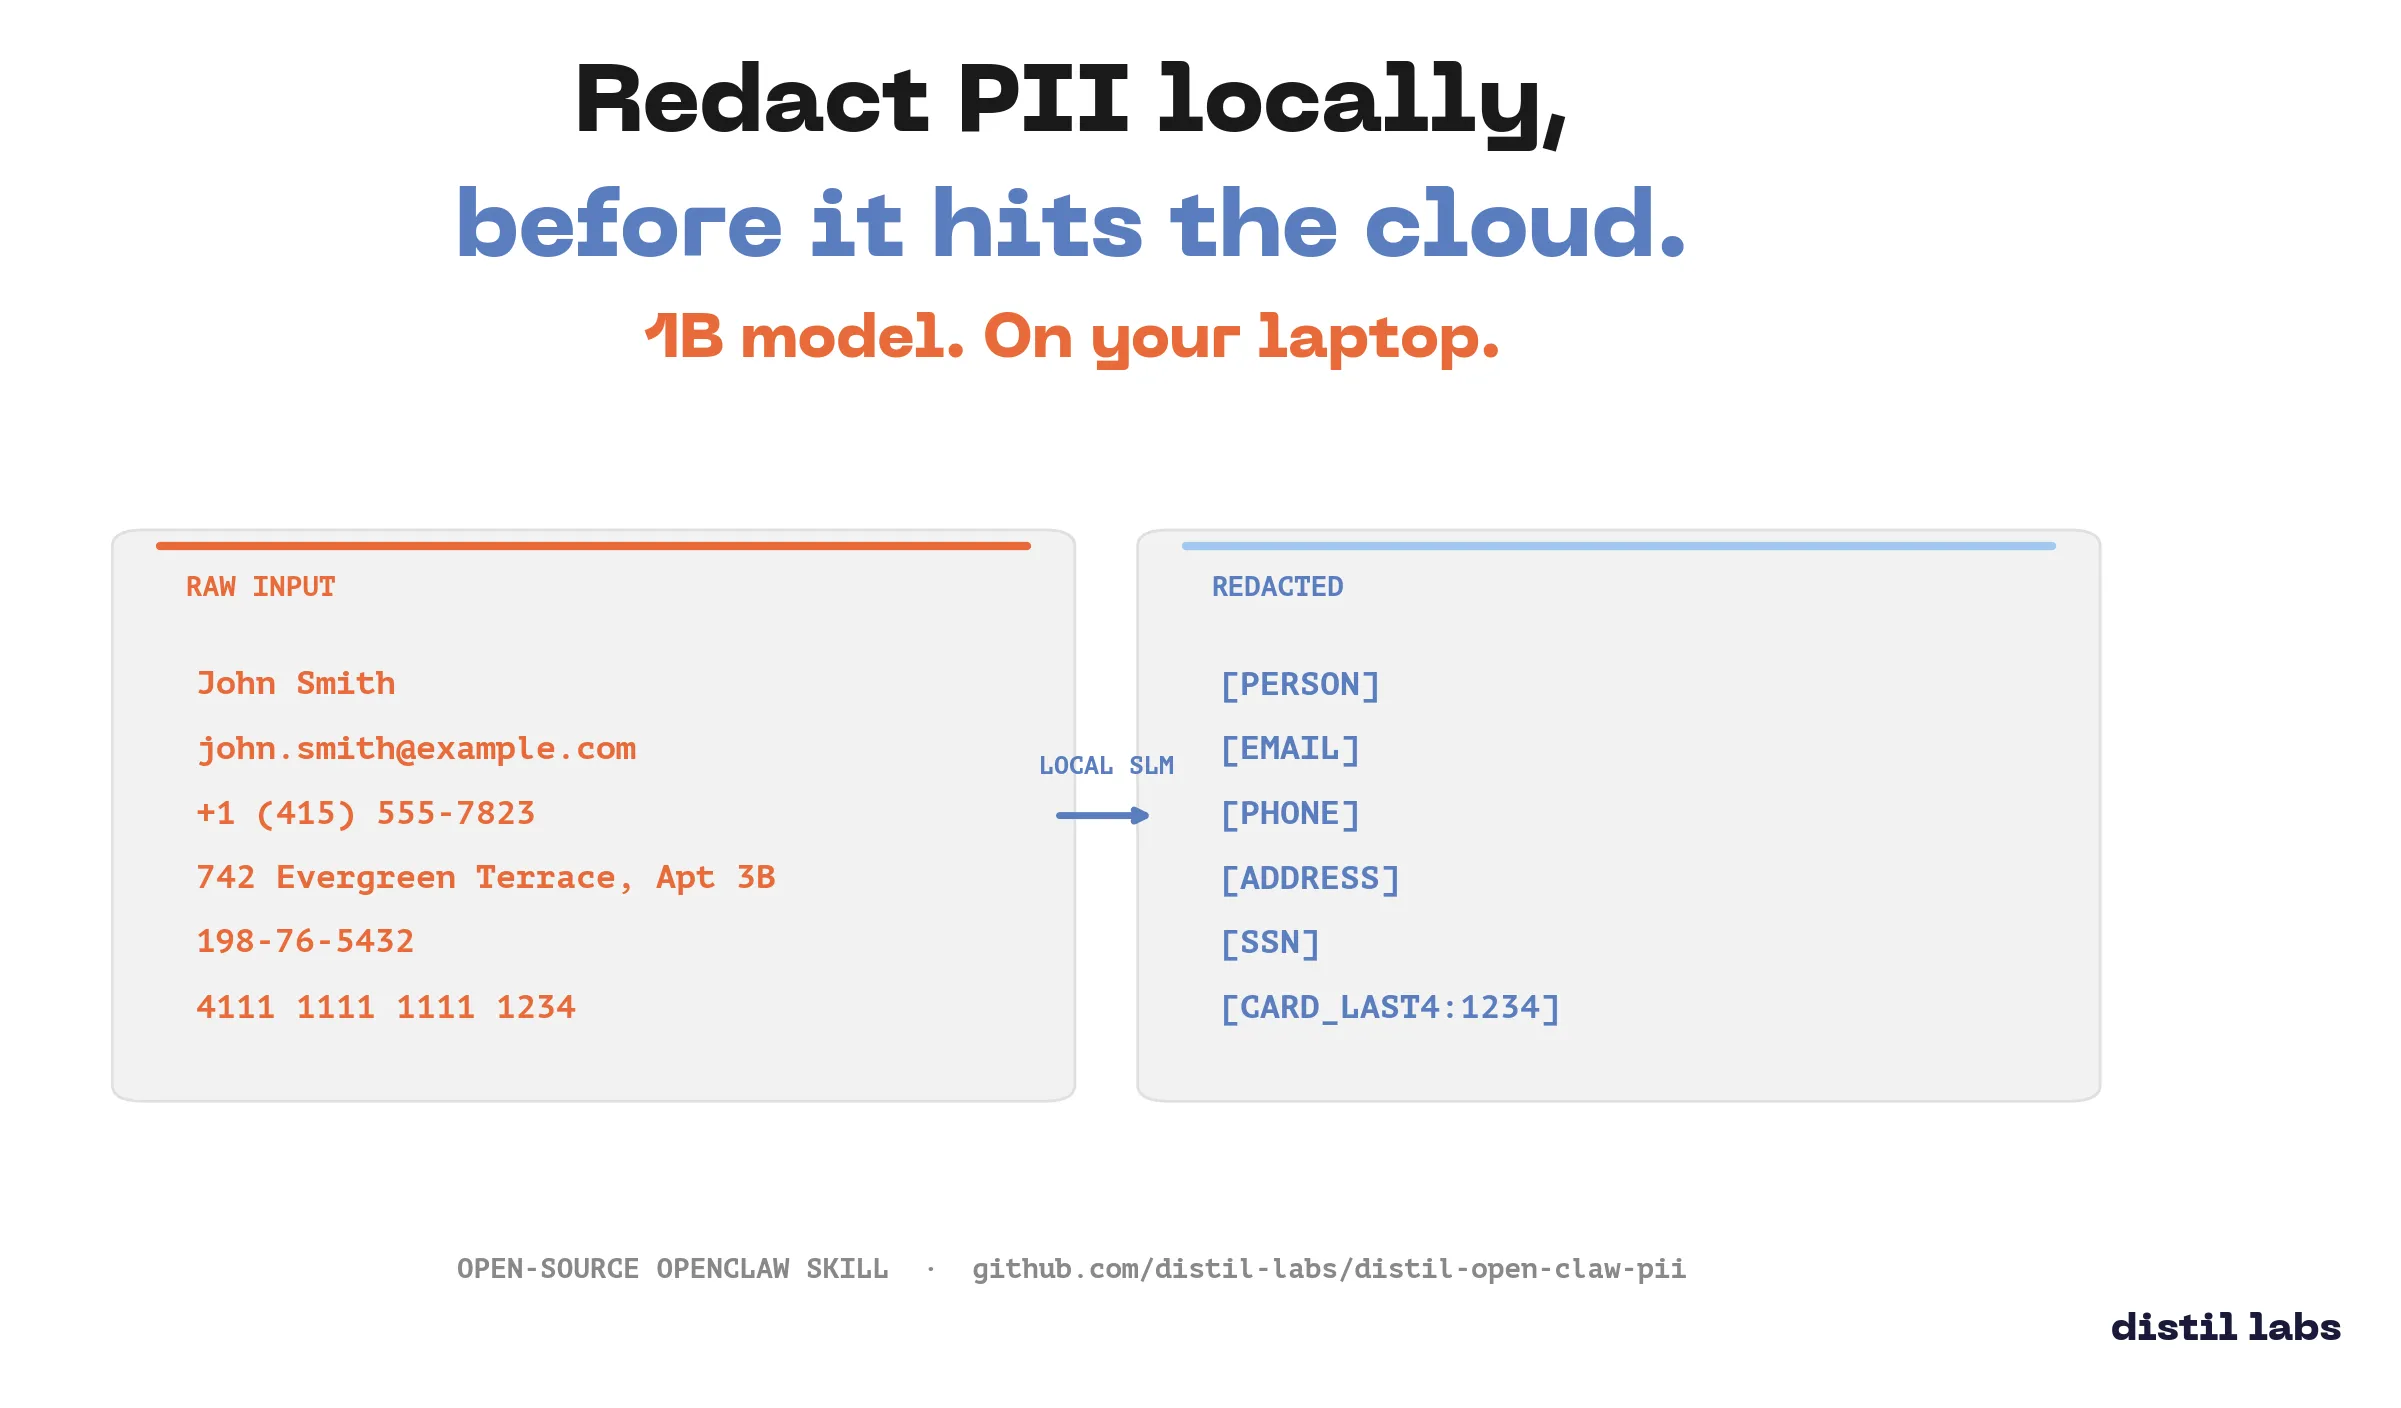
distil PII Redactor: an OpenClaw Skill
Locally redact PII from text using a fine-tuned 1B parameter model packaged as an OpenClaw skill. Your sensitive data never leaves your machine.